On Friday we published what we found screening 3,800 guest post domains. A reader made a short, correct objection: the method leaned on sitemaps, and sitemaps are written by the seller. A site running casino affiliate posts can simply leave them out.
He was right, so we rebuilt the check and ran it again. This is the method in full, including the parts that make it fail.
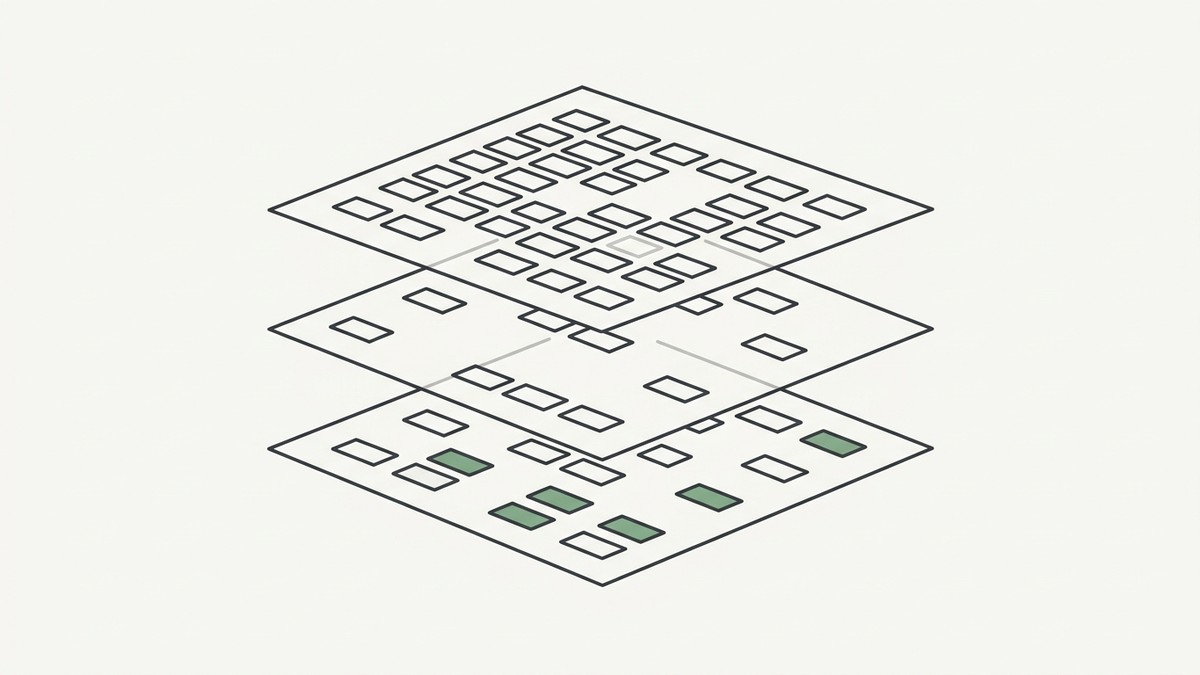
A site tells you three different stories
Ask a website what it publishes and you get three answers that do not match.
The sitemap is what the owner wants indexed. It is a file they generate, and anything can be left out of it.
The feed is what they published recently. Usually the last ten to fifteen items, so it shows the current operation and nothing older.
The index is what Google decided to keep. It cannot be curated by the site owner, which is exactly why it matters.
The interesting pages are the ones in the third list and not the first. On one site we checked, a domain presenting itself as an educational games platform, the sitemap and the feed were unremarkable. Google's index held casino pages, several aimed at a non-English market, and pages for cracked mobile apps.
What placed content actually looks like
Slugs full of casino and betting words are the easy case. These are the shapes that matter more, all of them found this week:
Pages under /wp-content/pages/?something-casino-something.html. That directory is for themes and plugins, not articles. Pages there are almost always injected into a compromised site, and they appear in neither the sitemap nor the feed.
Gambling content on a subdomain, or in an uploads folder, while the main site looks clean.
A tag page that exists only to collect essay-mill spam.
Promotional copy sitting behind bot protection, so the page loads for Google and challenges you.
A staging subdomain carrying the posts the main site would not host.
Then the checks that catch real publications by mistake
This is the part nobody writes about, and it is half the work.
Scan sitemap URLs for flag words and you will reject a construction trade magazine for covering Escorts Kubota, which makes tractors. You will reject an Indian fashion title for reporting on Kalyan Jewellers. You will reject a site for "slot booking system for property registration", which is a government appointment service, and for coverage of a politician named Pawan Kalyan.
You will reject a Canadian local newspaper for its own crime reporting: police seizing oxycodone, a child protection prosecution, a charity poker run, and a council debate about casino revenue. You will reject a men's magazine for writing about pornography and steroids in baseball, which is its subject. You will reject a business title for the phrase "betting on office spaces".
And you will reject a mental health service because the word "bet" appears inside its domain name. That one was ours, on the first run.
Across 3,804 domains the flags fell like this:
| category | domains flagged |
|---|---|
| gambling | 832 |
| adult | 307 |
| essay mills | 186 |
| pharma | 166 |
| follower selling | 123 |
| cracked software | 59 |
A keyword list alone would have thrown away hundreds of real publications.
So the flags are candidates, and something has to read them
The step that makes the difference is dull: fetch the flagged page, strip the navigation and scripts, and read it.
We ask a model one question about the text. Is this the site's own coverage of a subject, or content placed to promote an offer? A newspaper reporting a casino licence is the first. A page ranking casino bonuses with sign-up links is the second, whoever wrote it.
Of 383 domains with flagged pages in the index, that reading said 204 editorial and 152 placed, with 27 it could not resolve. Without it we would have discarded 204 working publications.
Two checks that only work as a pair
Posts per day, taken from the feed's own dates. Whether the recent titles share a subject.
Neither works alone. A local newspaper we checked publishes 22 times a day and a men's magazine 76, and both are entirely real. A site publishing fifteen unrelated commissions a day is a mill. So: high volume with a subject is a newsroom, high volume without one is a mill, low volume without one is a dormant blog taking placements.
We also found that this pair over-flags badly on its own. Of the sites it sent for review, three quarters had nothing in the index to justify the suspicion. It generates candidates. It does not convict.
Adding a probability, because a verdict is not enough
Our own reading was unstable. One site came back as a real magazine one day and a content mill the next.
So every flagged page now also goes to a typed judgment service that returns the same editorial-or-placed answer with a confidence attached. On 364 domains the two agreed 88 percent of the time, and the disagreements sat where confidence was low, which is what a calibrated score should do.
That turns an argument into a workflow: accept above 0.9, reject below 0.1, and send the middle to a person. On our shelf that left about 40 percent of flagged sites needing human judgment, which is the honest amount.
What it did to our numbers
| stage | domains |
|---|---|
| marketplace listings mirrored | 159,736 |
| passed the original homepage screen | 3,442 |
| pass every content check | 2,051 |
| still pass when the whole thing is run a second time | 1,465 |
That last line matters. We ran the full screen twice on different days and discarded anything that changed its mind, 147 sites. A verdict that flips between runs is not a verdict, and for a shelf you would sell from, the tie goes against the site.
So about 0.9 percent of the original catalogue, down from the 2 percent we published in August. We tightened the screen this month after a review of our own placements found sites the earlier version should not have passed. The original screen, and the 159,736 listings it ran on, are described in the marketplace study.
What it costs, if you want to run it yourself
Sitemap, feed and outbound-link checks are free. The index check is two search queries per domain, about half a penny on our provider, and you must never try to enumerate a large site, because you pay per ten results. Query the index with your flag words instead. Reading the flagged pages costs a fraction of a penny each. Screening 1,700 domains cost us about fifteen dollars and a day of background time.
What this proves, and what it does not
It shows that a homepage tells you almost nothing, that a sitemap tells you what a seller is willing to admit, and that the index is the only one of the three the seller does not control.
It does not show our screen is right. It produced its own false positives on day one, its judgments move between runs, and everything here comes from one snapshot of two marketplaces plus one supplier list in September 2026. Absence of evidence is the weakest result we produce: finding nothing means we found nothing, not that there is nothing.
One last thing, in the spirit of publishing what happens. Friday's post about this work was crawled by Google within a minute and, three days later, is still not indexed. A piece about detecting spam that reads, to a classifier, like the thing it describes. Every page we publish is timed on the live log, including that one.